Publications
A collection of my research work.
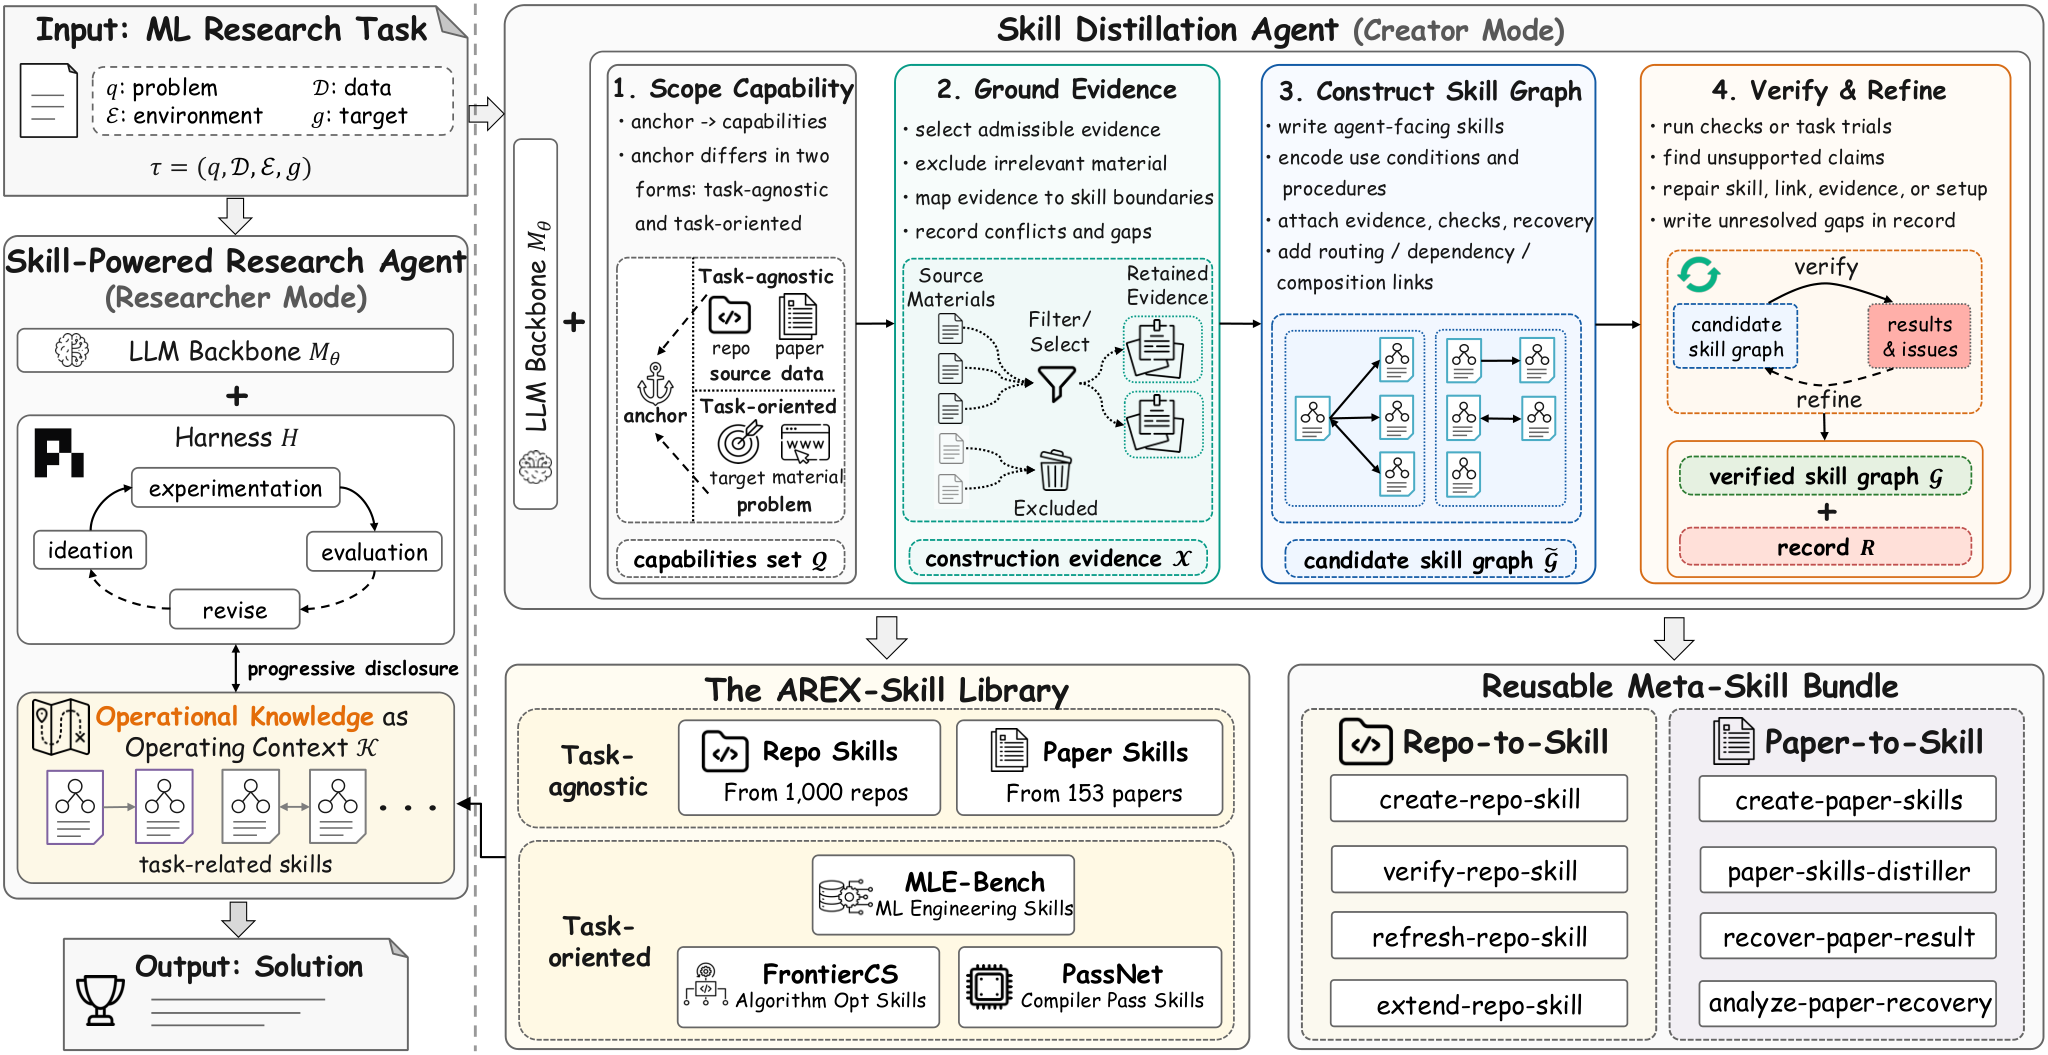
Repo-To-Skill: Distilling GitHub Repositories Into AI4AI Skills
Jianlyu Chen*, Yuyang Hu*, Hongjin Qian*, Jiawei Liu*, et al.
CoRR 2026
DisCo distills operational knowledge from machine-learning repositories into compact, verified skills that autonomous research agents can reuse across tasks.
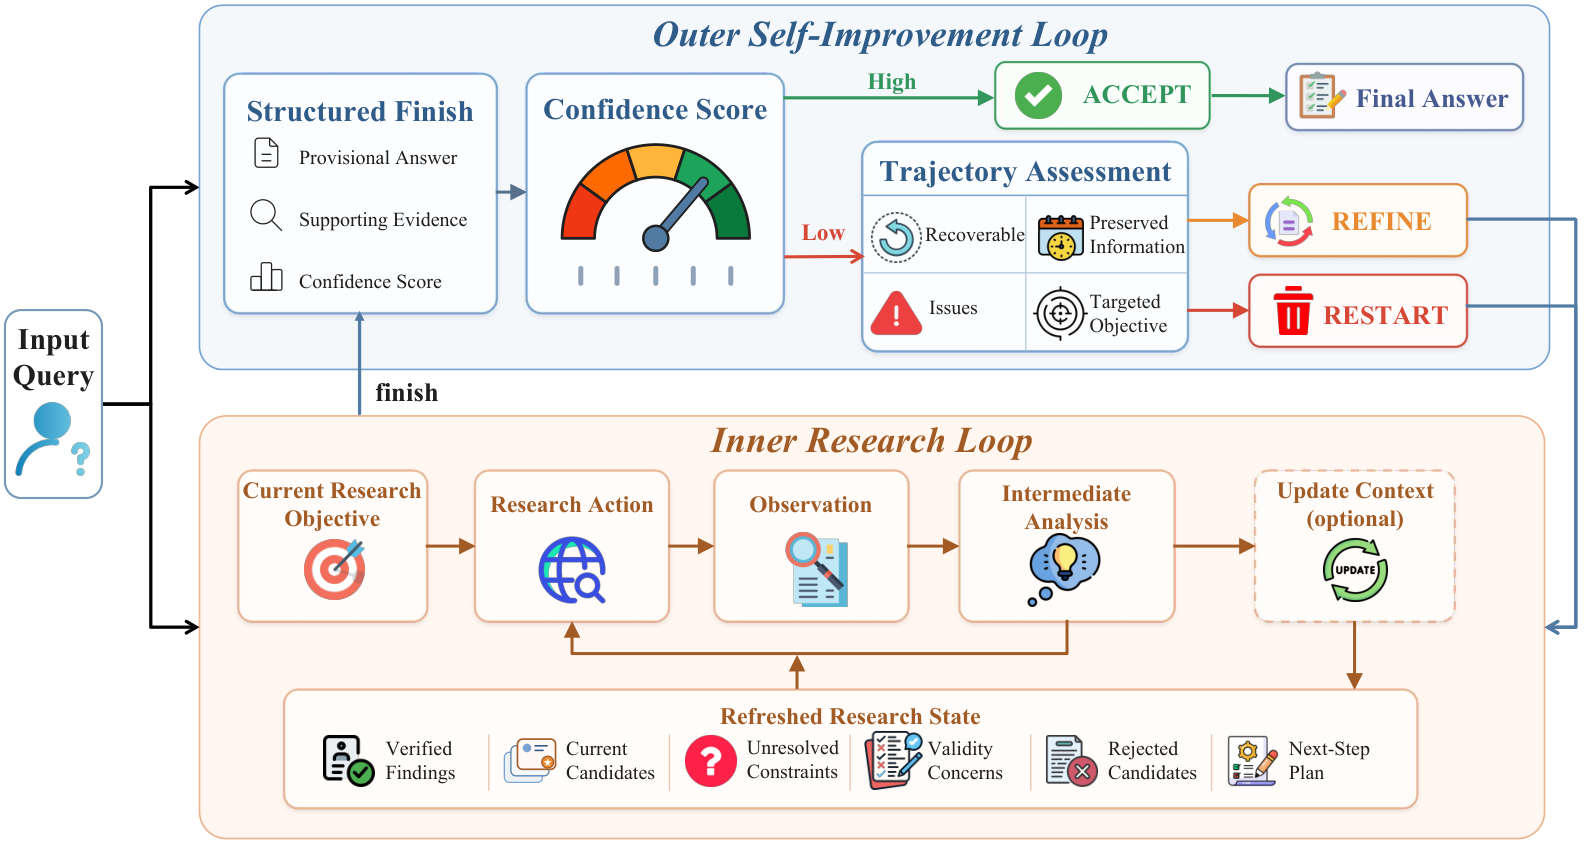
AREX: Towards a Recursively Self-Improving Agent for Deep Research
Shuqi Lu, Chaofan Li, Kun Luo, Zhang Zhang, et al.
CoRR 2026
A recursively self-improving deep-research agent that alternates research and constraint-wise verification while maintaining a compact improvement state.
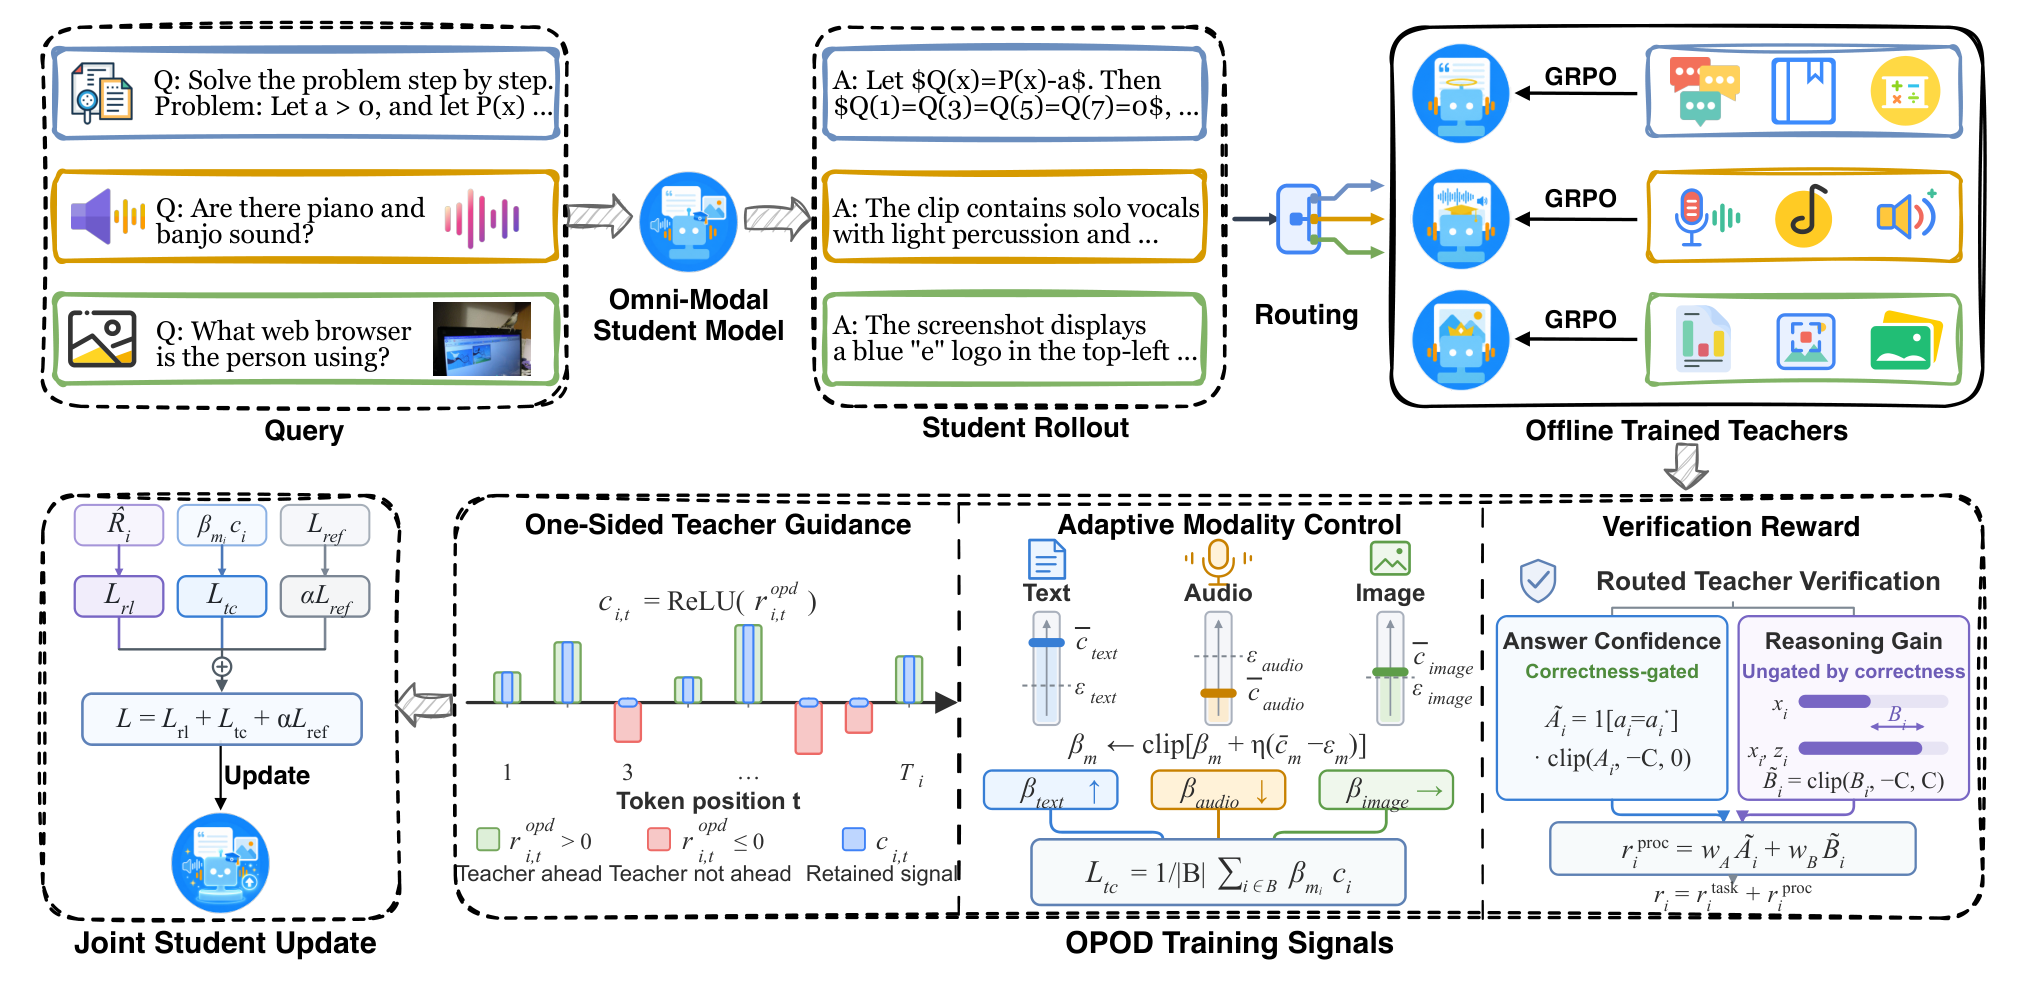
OPOD: On-Policy Omni Distillation
Tong Zhao, Yuyang Hu, Reed Li, Yu Lu, et al.
CoRR 2026
An on-policy distillation method that coordinates modality-specific teachers to improve a single deployable omni-modal model.
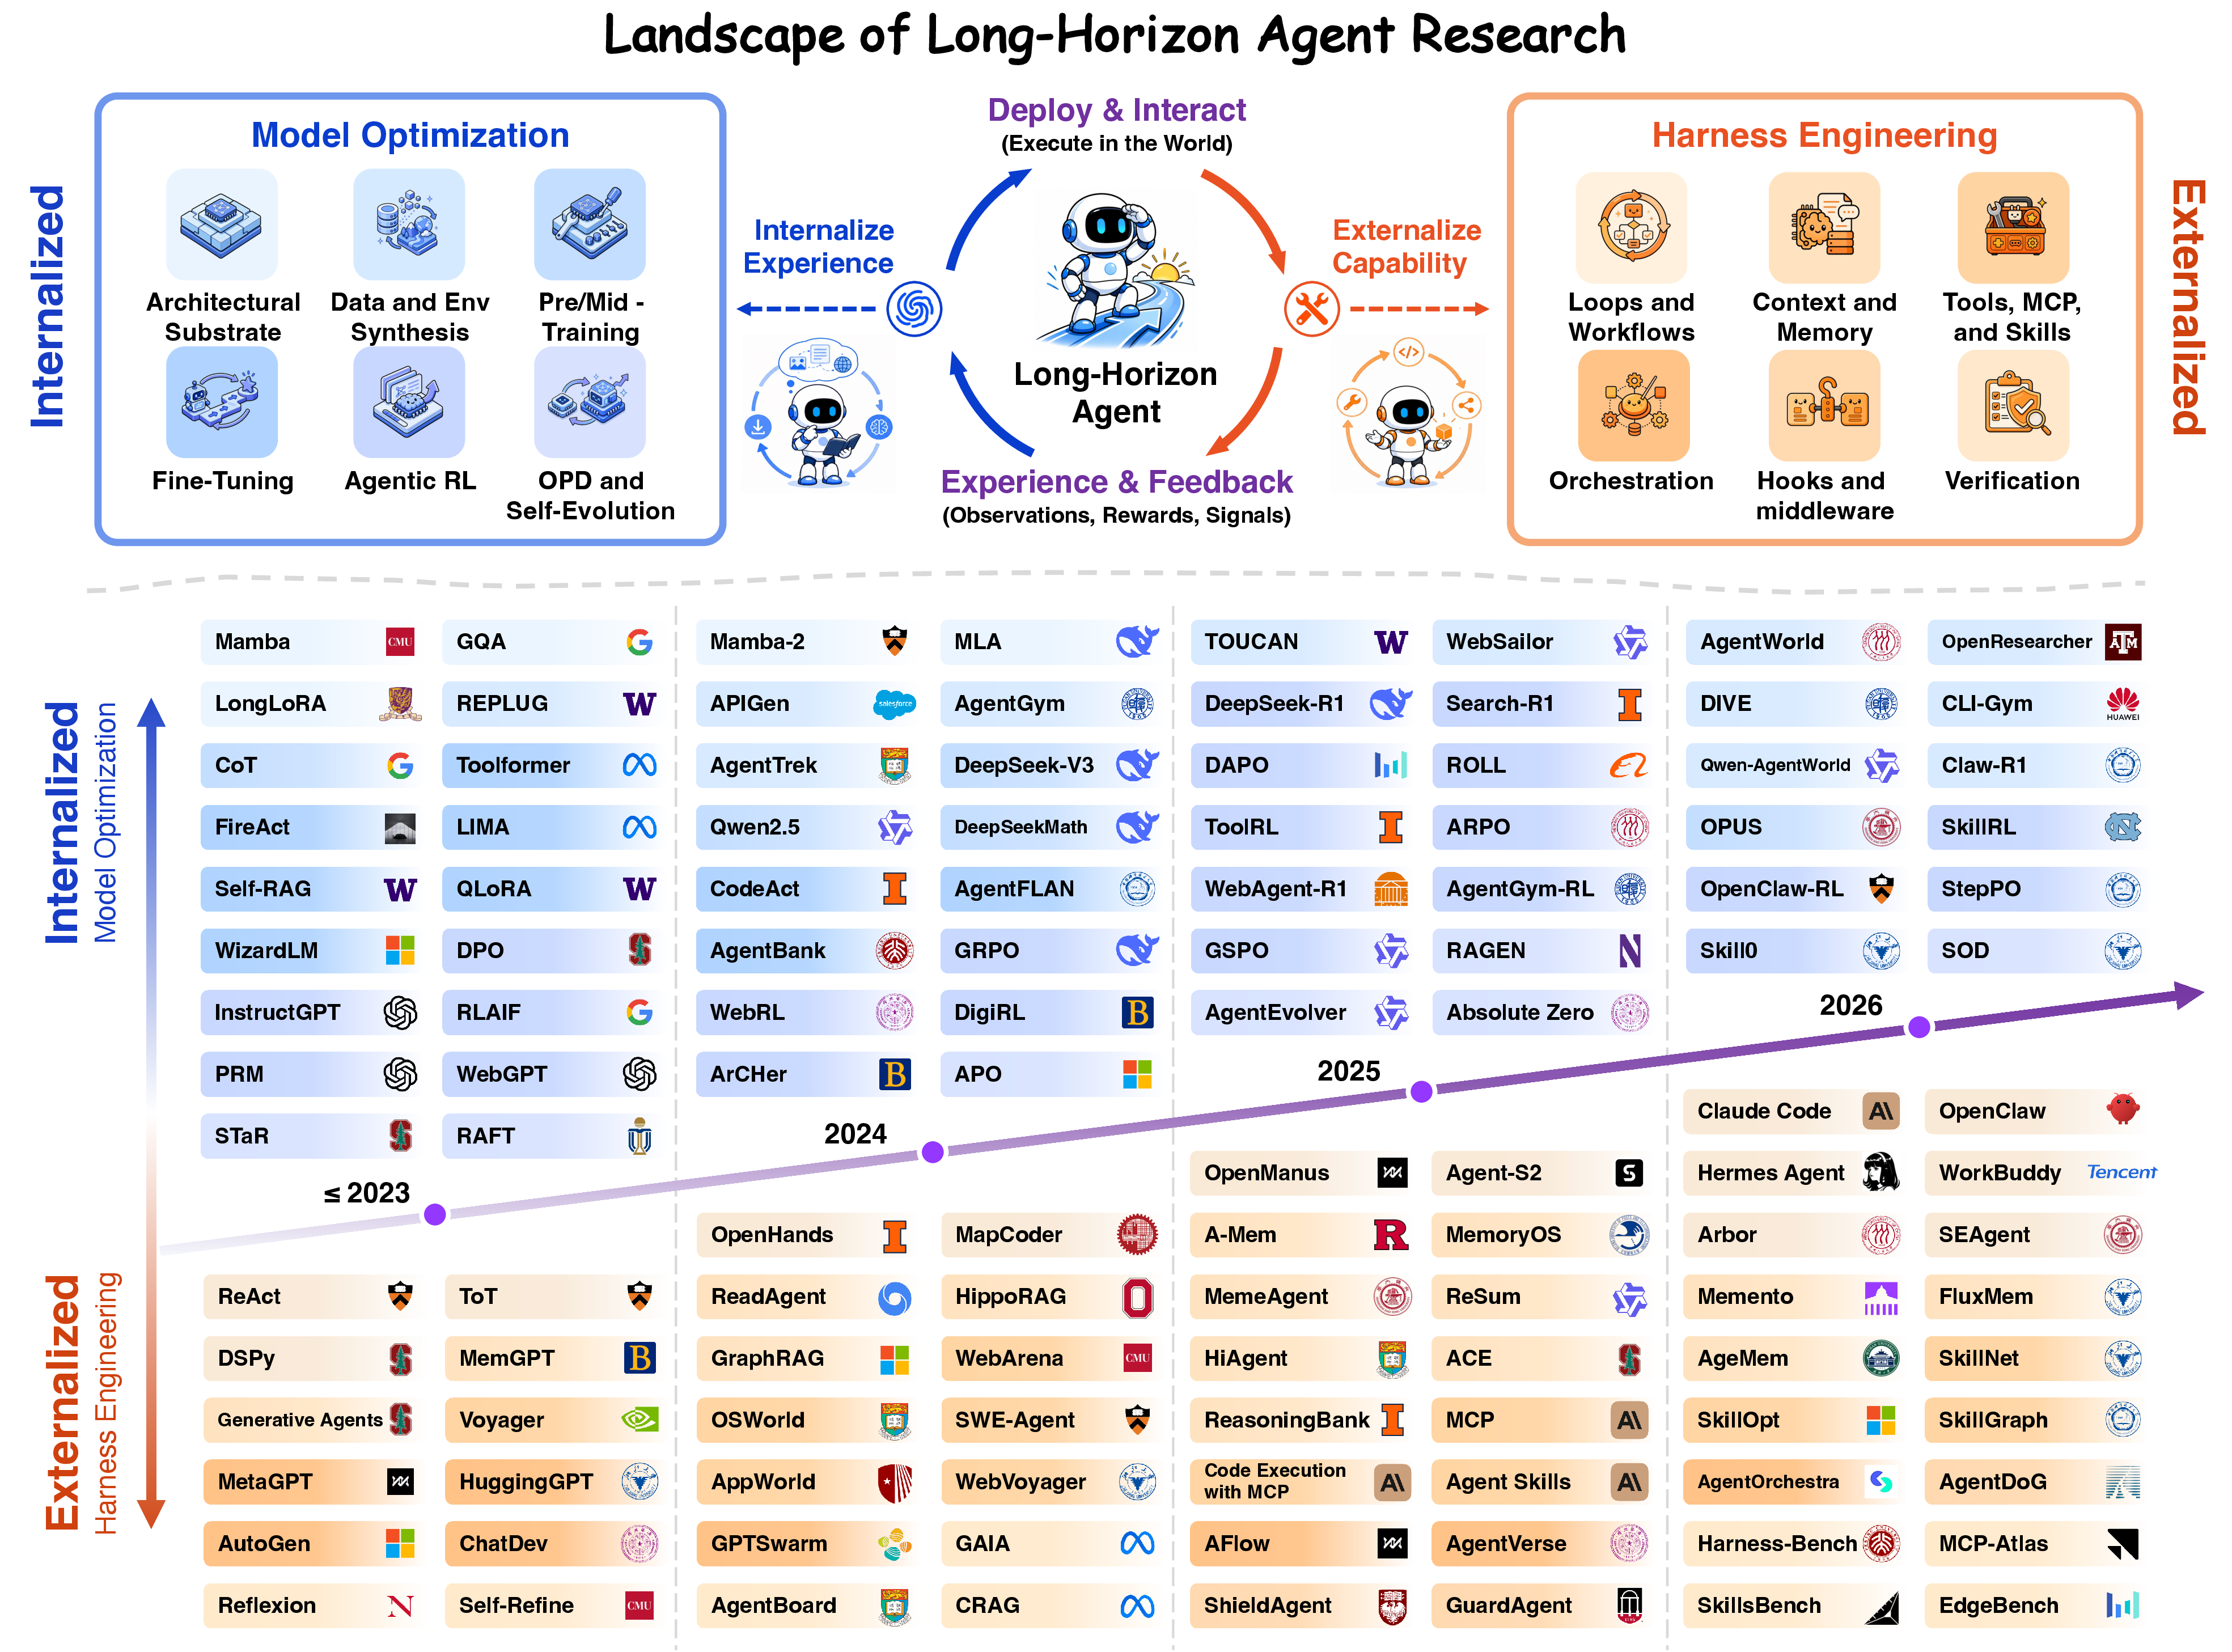
Towards Long-Horizon Agents: A Survey
Guanting Dong, Xiaoshuai Song, Yuyang Hu, Jiajie Jin, et al.
Preprints 2026
A unified survey of long-horizon agency organized around foundation, evolution, harness, optimization, application, and frontier perspectives.
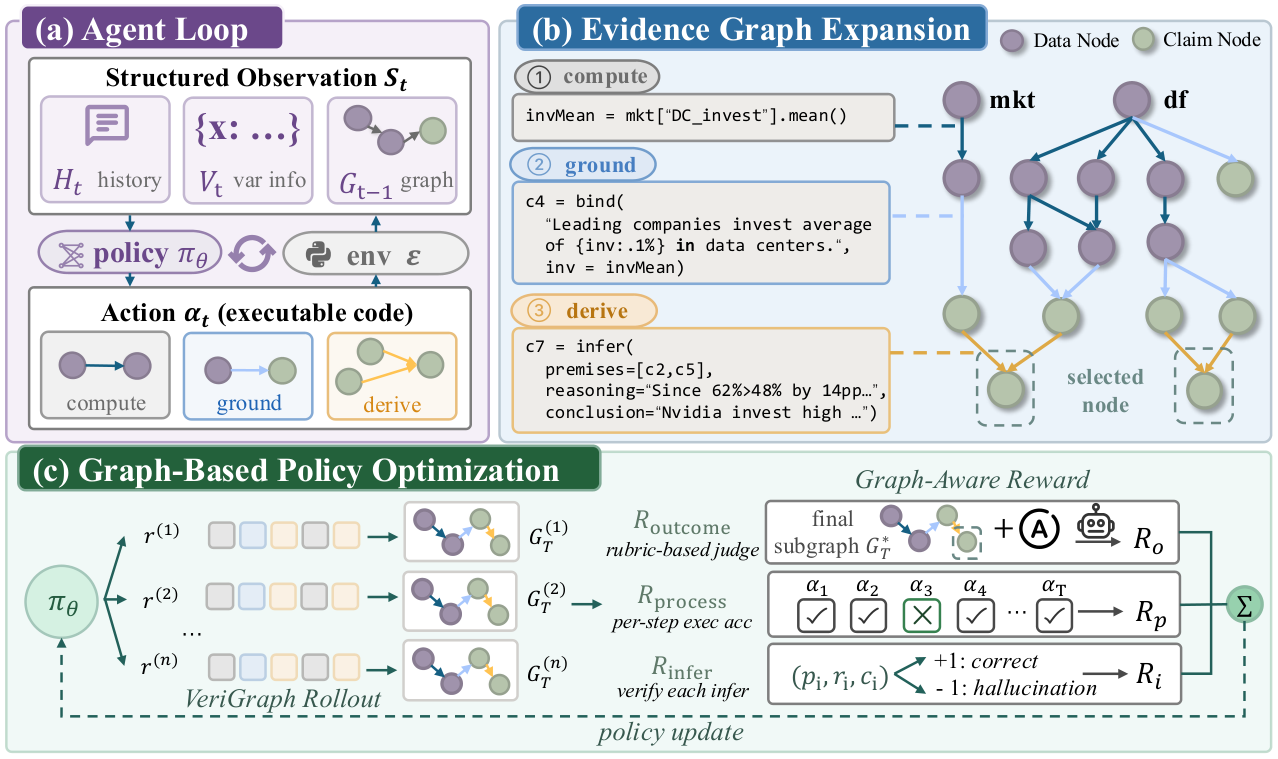
VeriGraph: Towards Verifiable Data-Analytic Agents
Jiajie Jin, Zhao Yang, Wenle Liao, Yuyang Hu, et al.
CoRR 2026
A traceable neuro-symbolic framework that constructs explicit evidence graphs for auditable data analysis and claim-level verification.
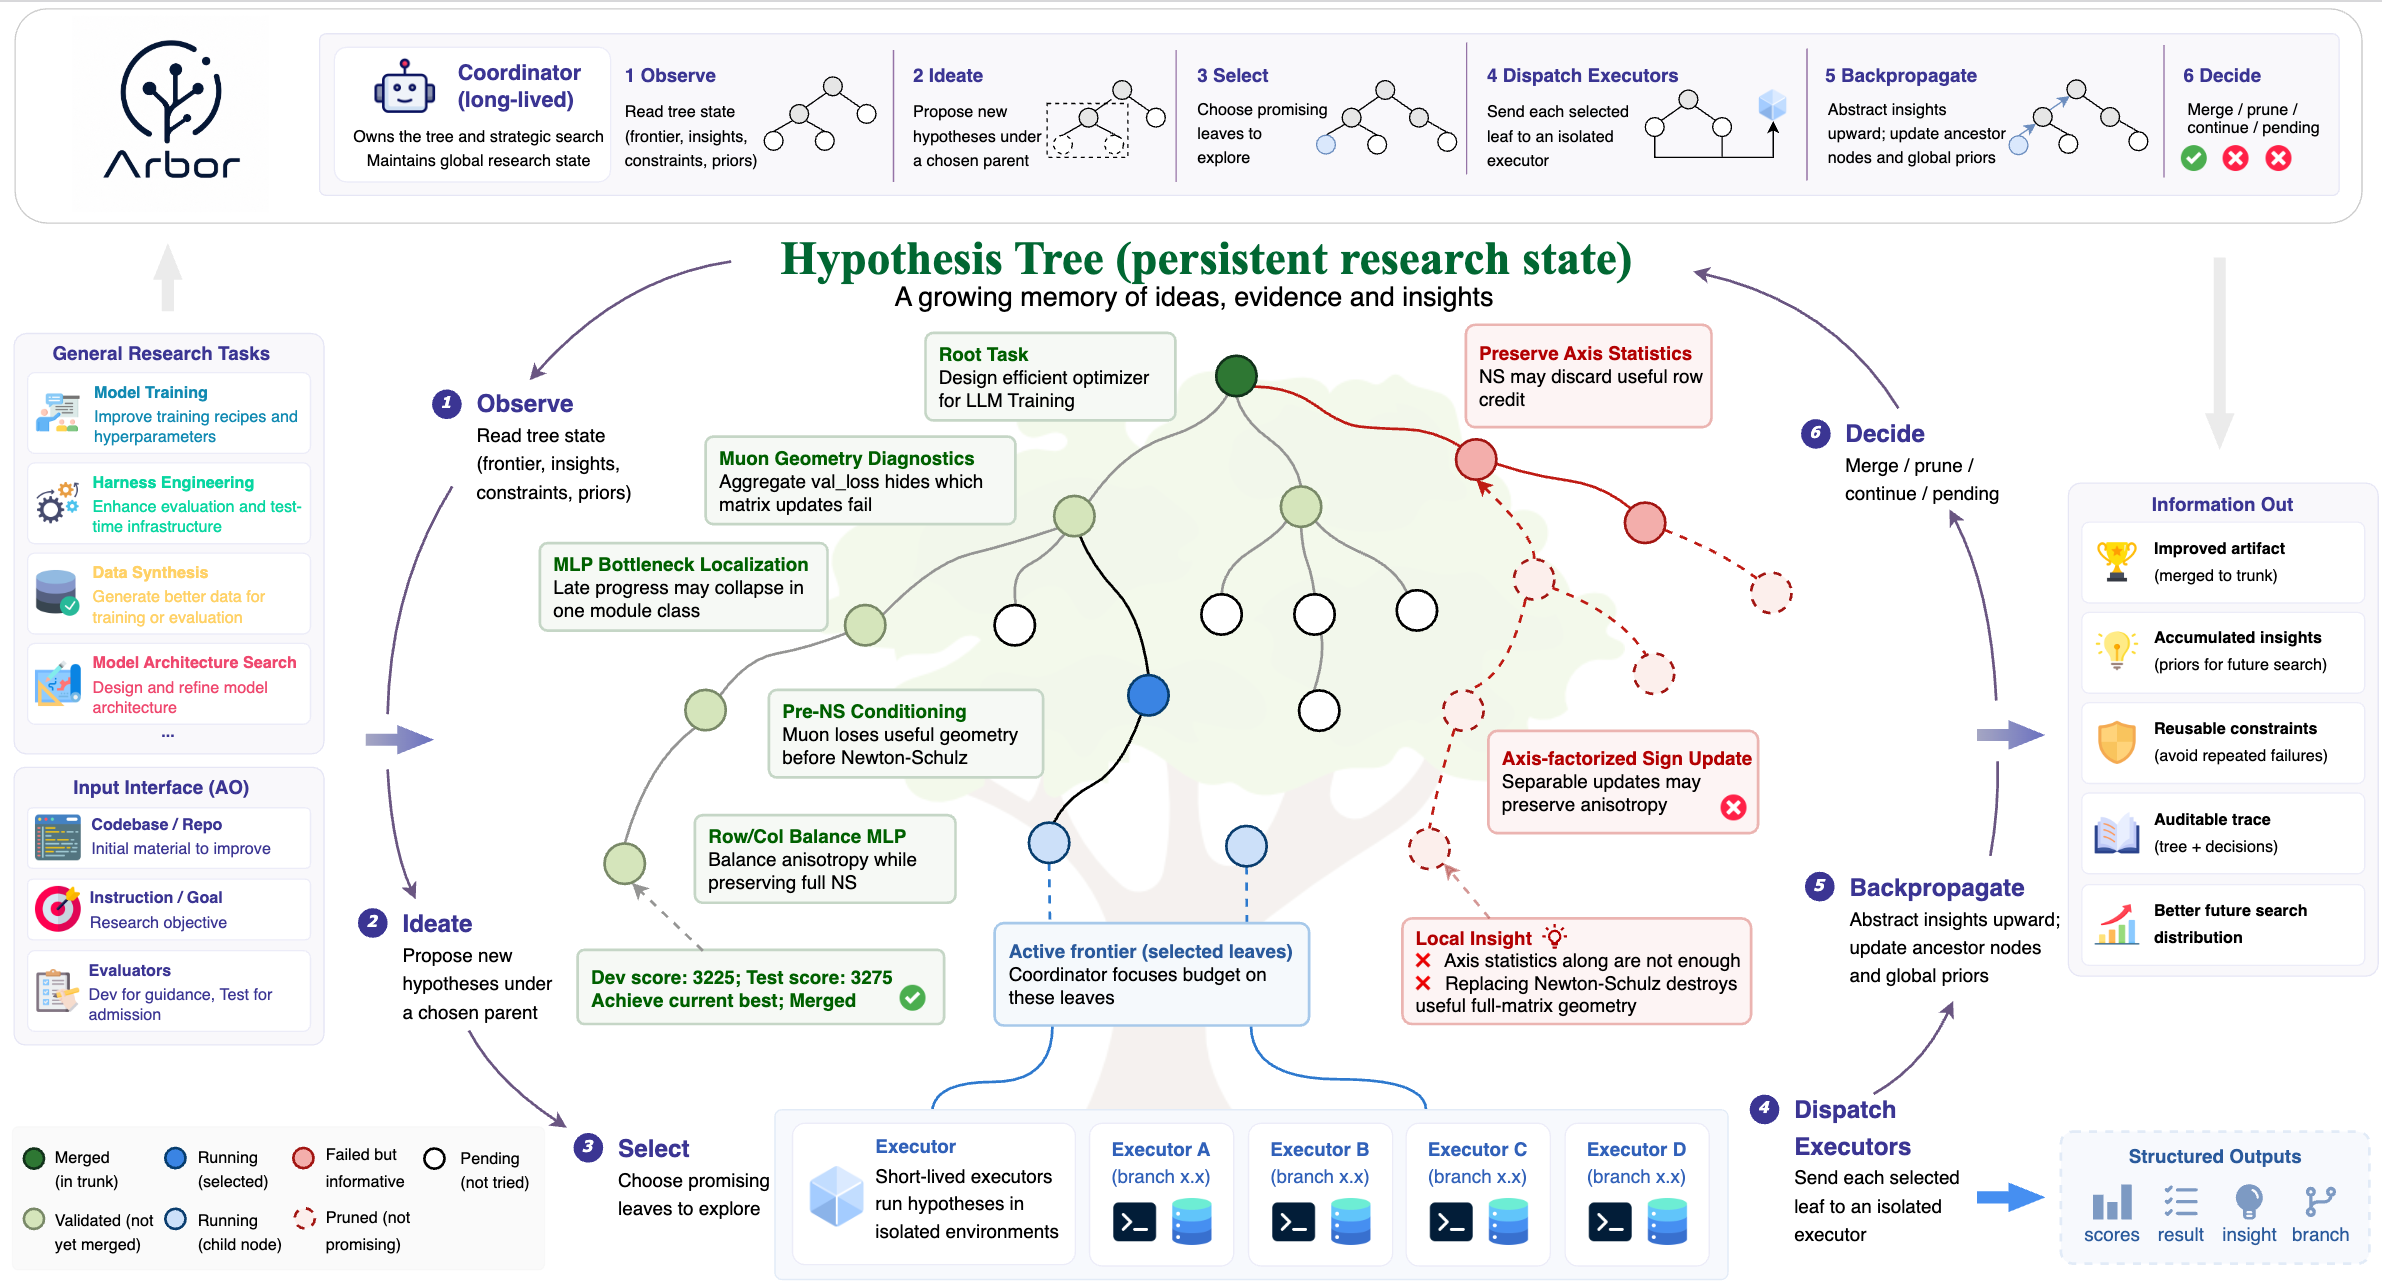
Toward Generalist Autonomous Research via Hypothesis-Tree Refinement
Jiajie Jin*, Yuyang Hu*, Kai Qiu, Qi Dai, et al.
CoRR 2026
Arbor combines a long-lived coordinator, isolated executors, and persistent hypothesis-tree refinement for cumulative autonomous research.
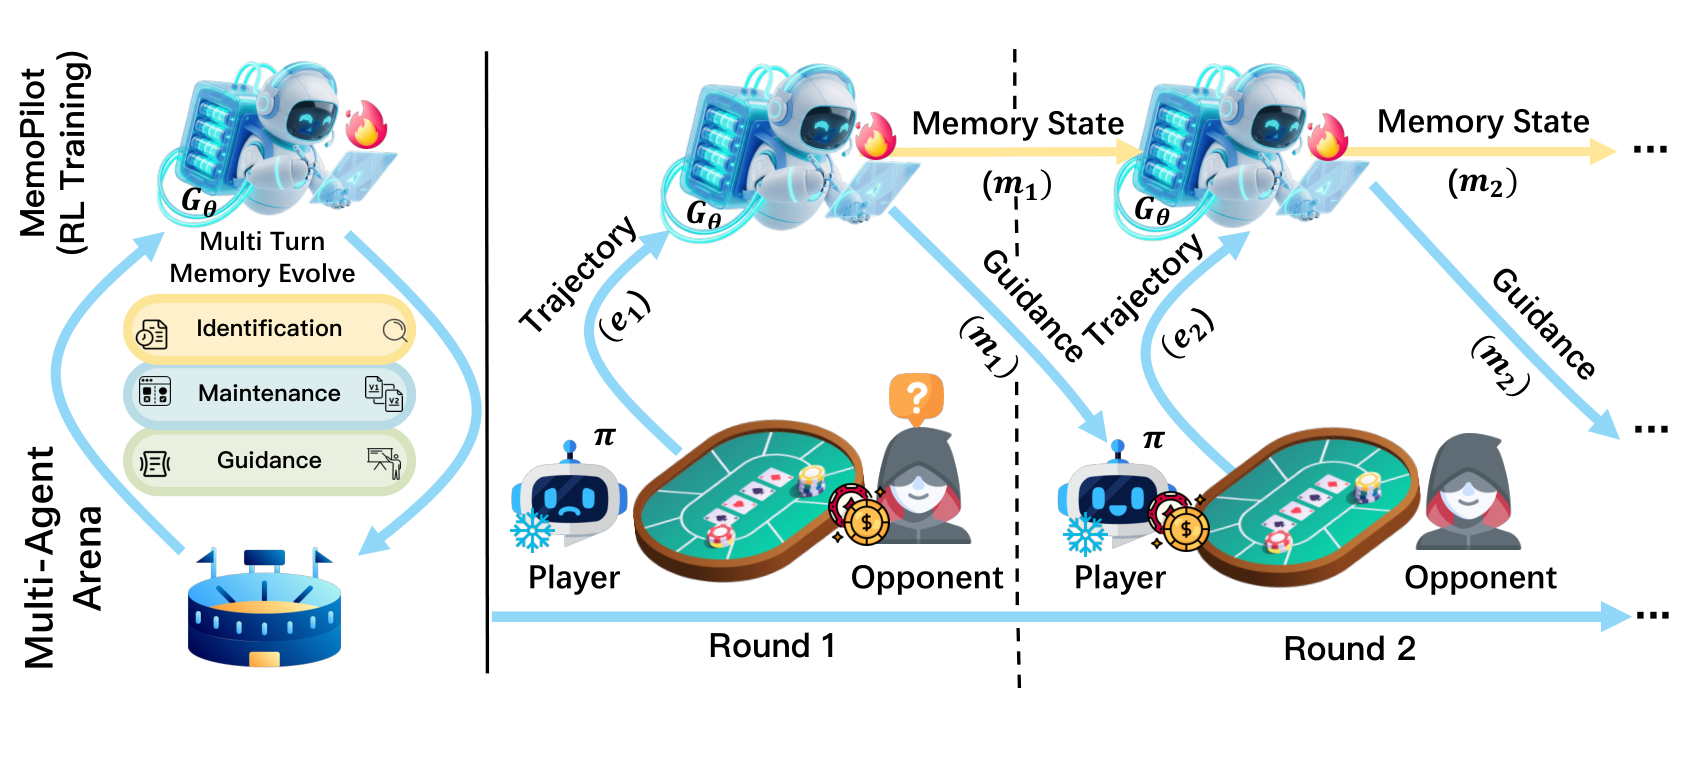
From Player to Master: Enhancing Test-Time Learning of LLM Agents via Reinforcement Learning over Memory
Yishuo Cai, Xingyu Guo, Xuancheng Huang, Jinhua Du, et al.
CoRR 2026
MemoPilot trains a plug-in memory copilot end-to-end to improve a frozen language-model agent across sequential interactions.
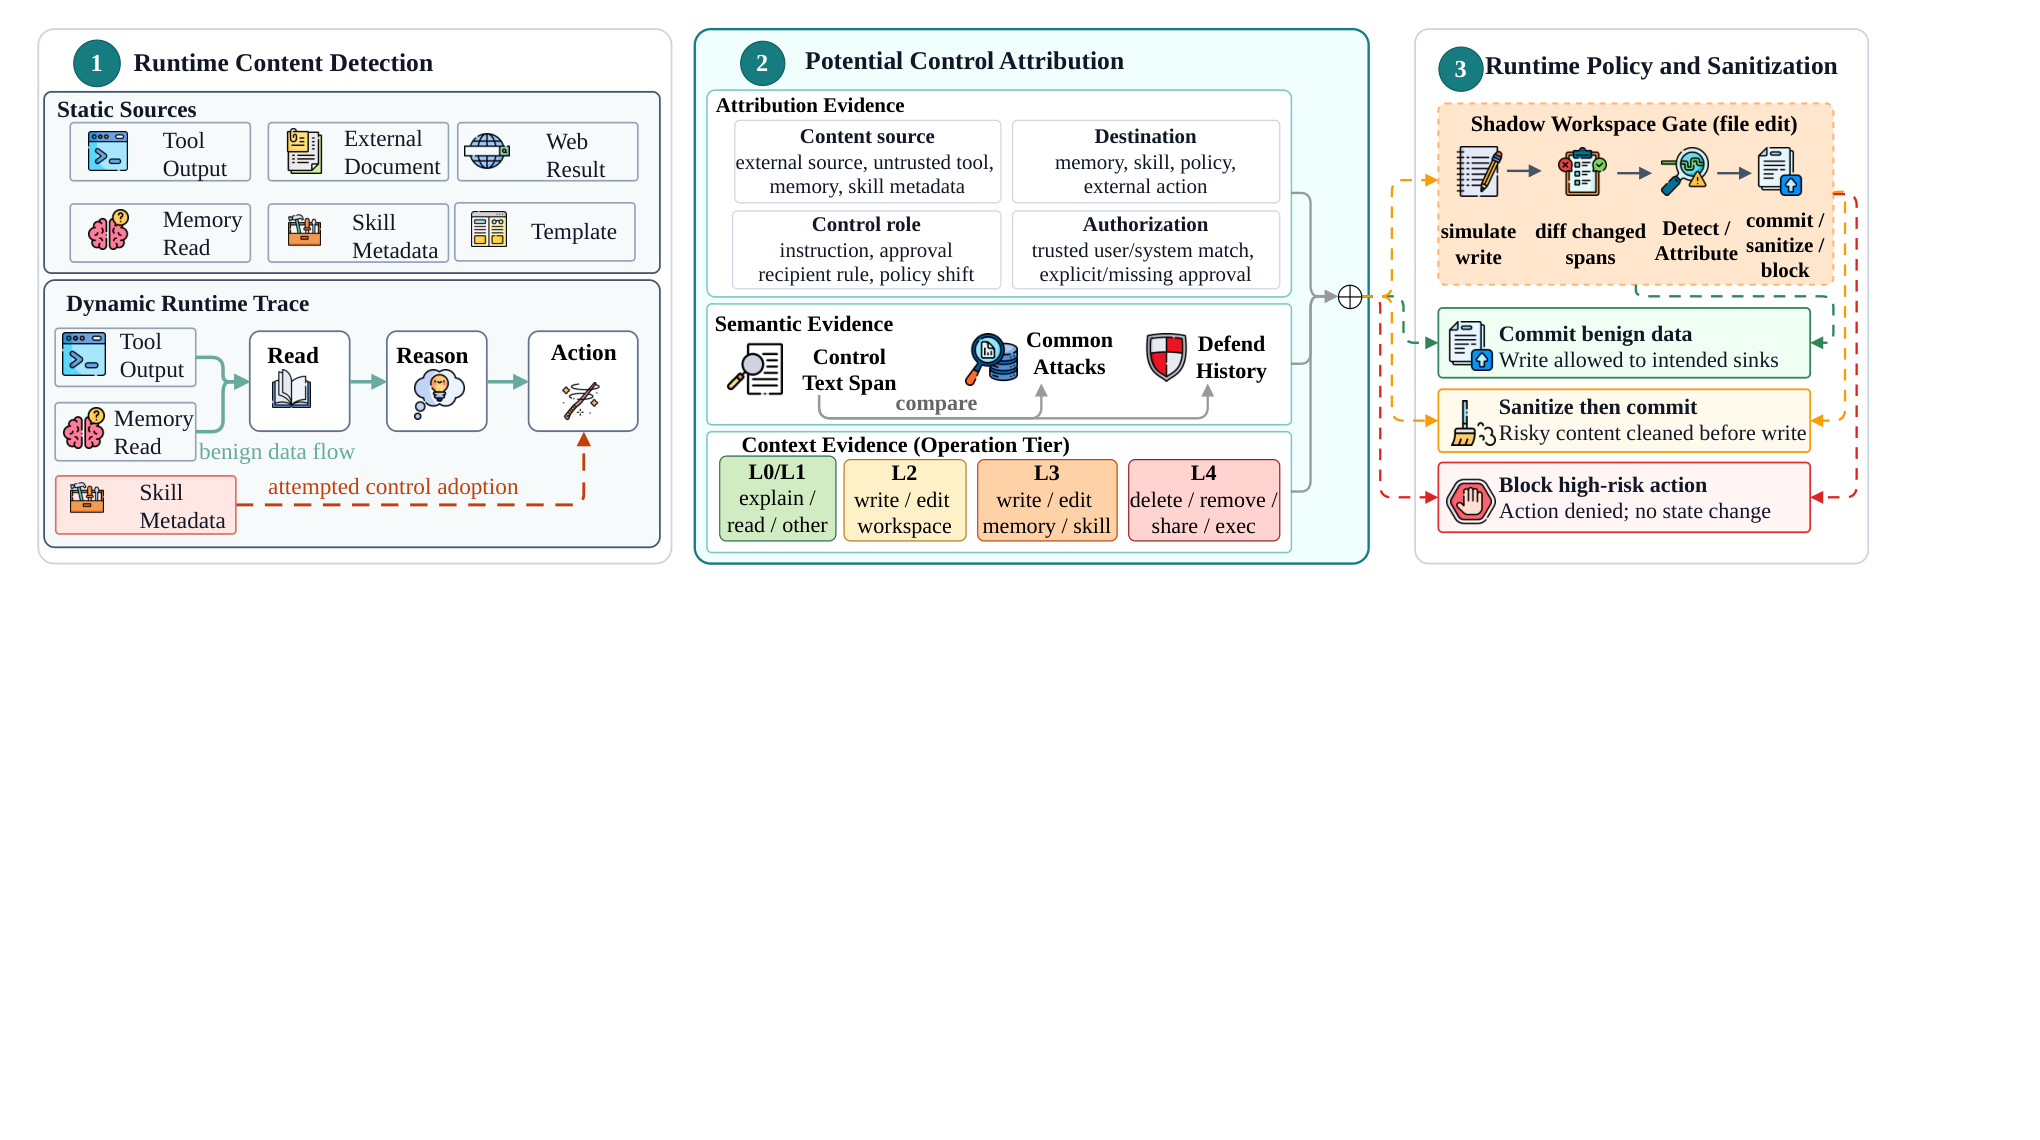
From Prompt Injection to Persistent Control: Defending Agentic Harness Against Trojan Backdoors
Jiejun Tan, Zhicheng Dou, Xinyu Yang, Yuyang Hu, et al.
CoRR 2026
ClawTrojan exposes multi-step persistent-control attacks in local agentic harnesses, while DASGuard traces and sanitizes untrusted control content.
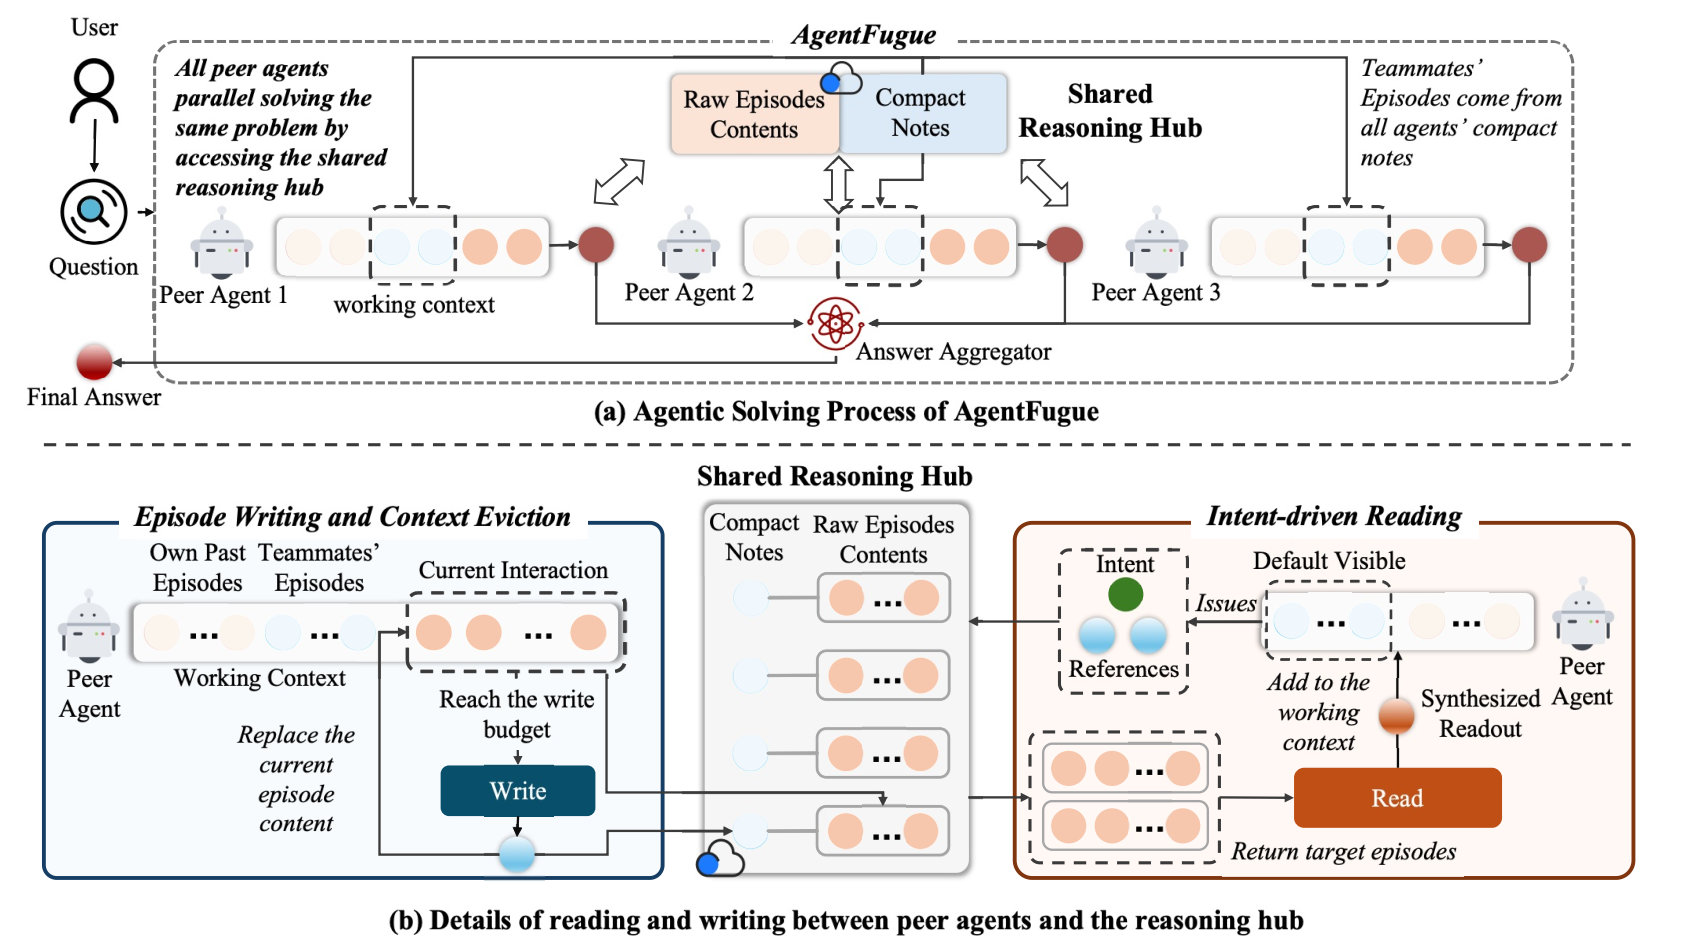
AgentFugue: Agent Scaling for Long-Horizon Tasks through Collective Reasoning
Yuyang Hu, Hongjin Qian, Shuting Wang, Jiongnan Liu, et al.
CoRR 2026
A collective reasoning framework that lets peer agents share reusable intermediate reasoning through a shared reasoning hub for long-horizon tasks.
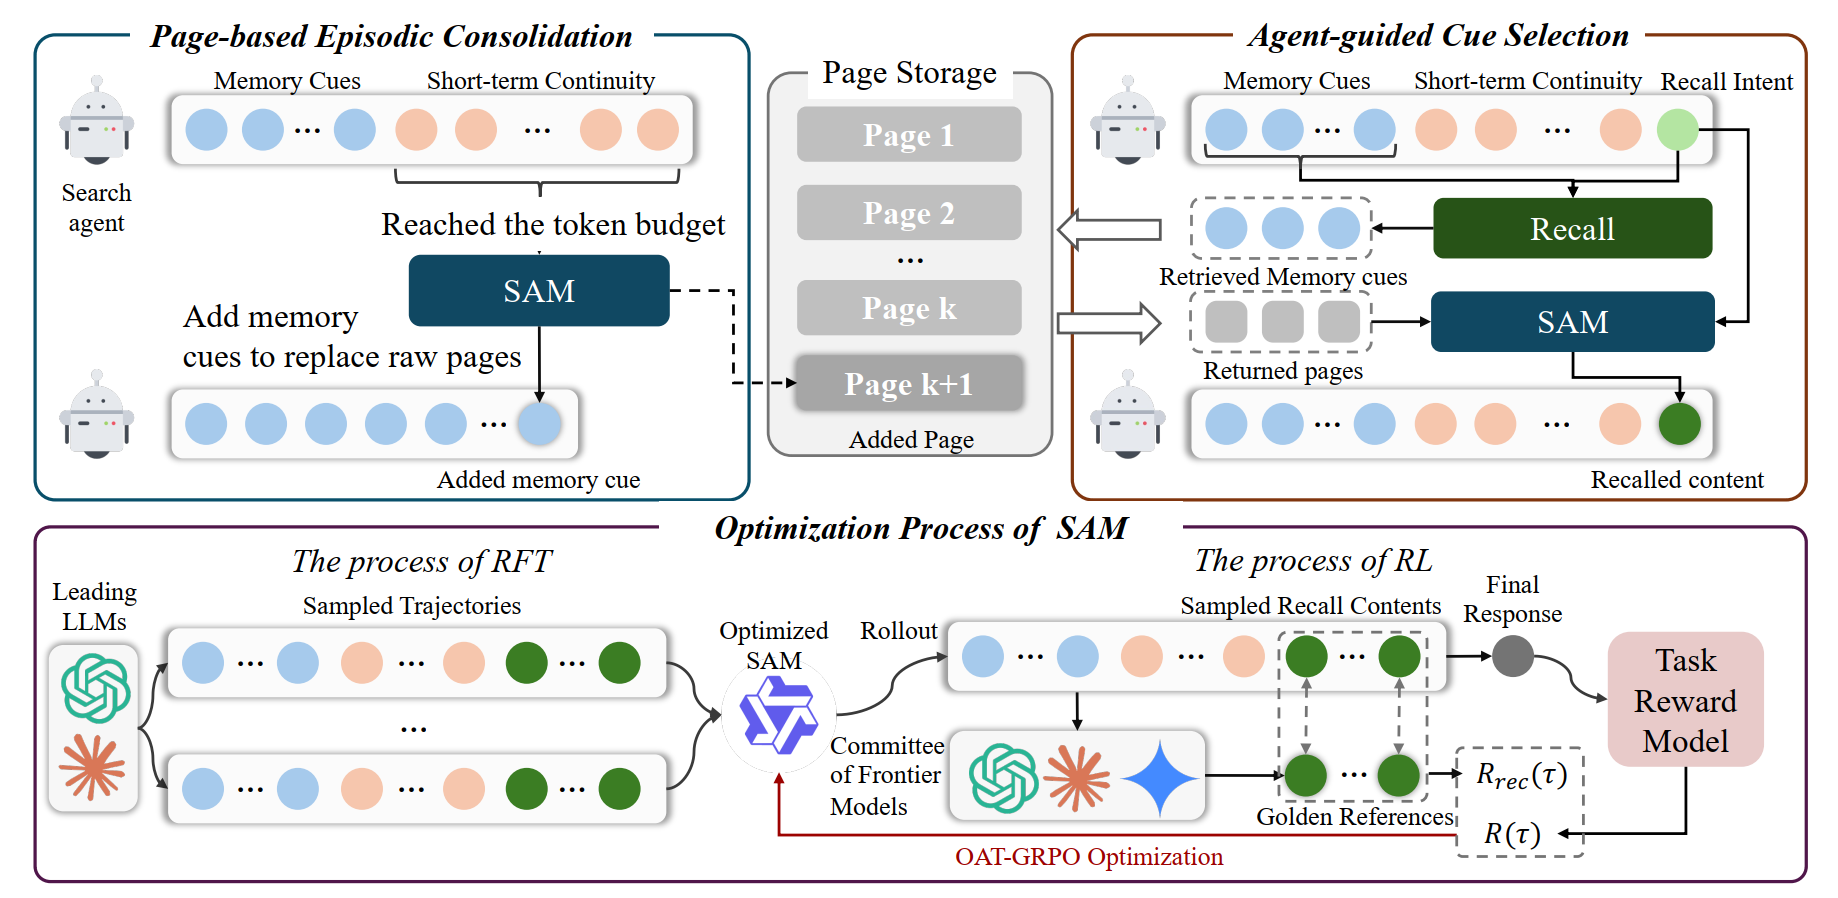
SAM: State-Adaptive Memory for Long-Horizon Reasoning Agent
Yuyang Hu, Hongjin Qian, Shuting Wang, Jiongnan Liu, et al.
CoRR 2026
A state-adaptive memory framework that preserves raw trajectory pages while using compact memory cues for intent-driven recall in long-horizon agents.
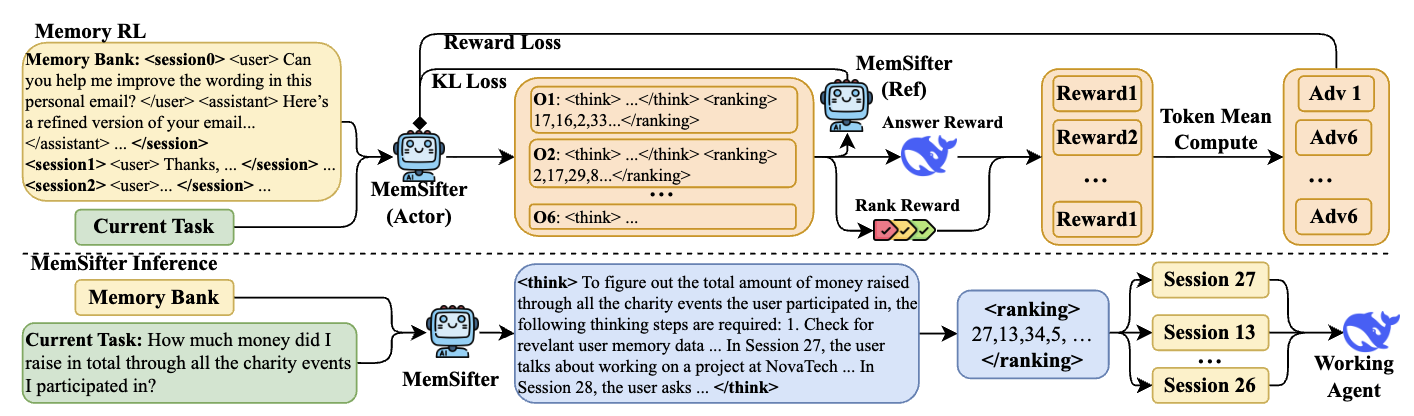
MemSifter: Offloading LLM Memory Retrieval via Outcome-Driven Proxy Reasoning
Jiejun Tan, Zhicheng Dou†, Liancheng Zhang, Yuyang Hu, et al.
CoRR 2026
A proxy-reasoning framework that offloads LLM memory retrieval to a smaller model and optimizes retrieval through outcome-driven reinforcement learning.
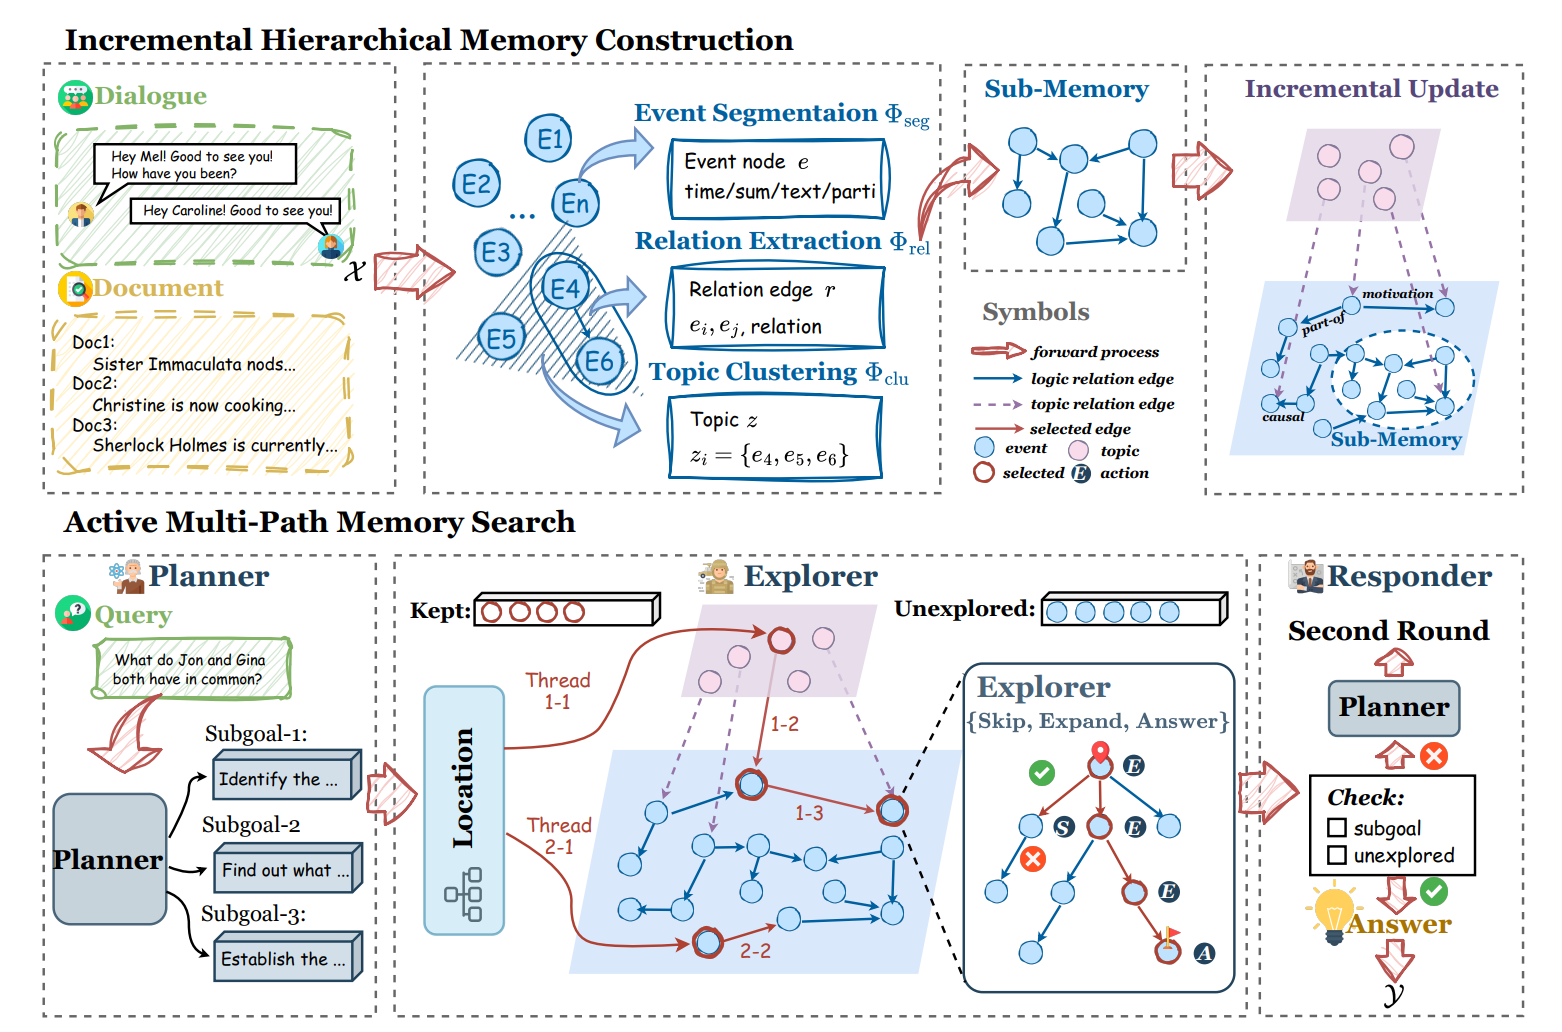
Memory Matters More: Event-Centric Memory as a Logic Map for Agent Searching and Reasoning
Yuyang Hu, Jiongnan Liu, Jiejun Tan, Yutao Zhu, et al.
ACL Findings 2026
An event-centric memory framework that organizes agent experiences into an event graph for logic-aware memory search and reasoning.
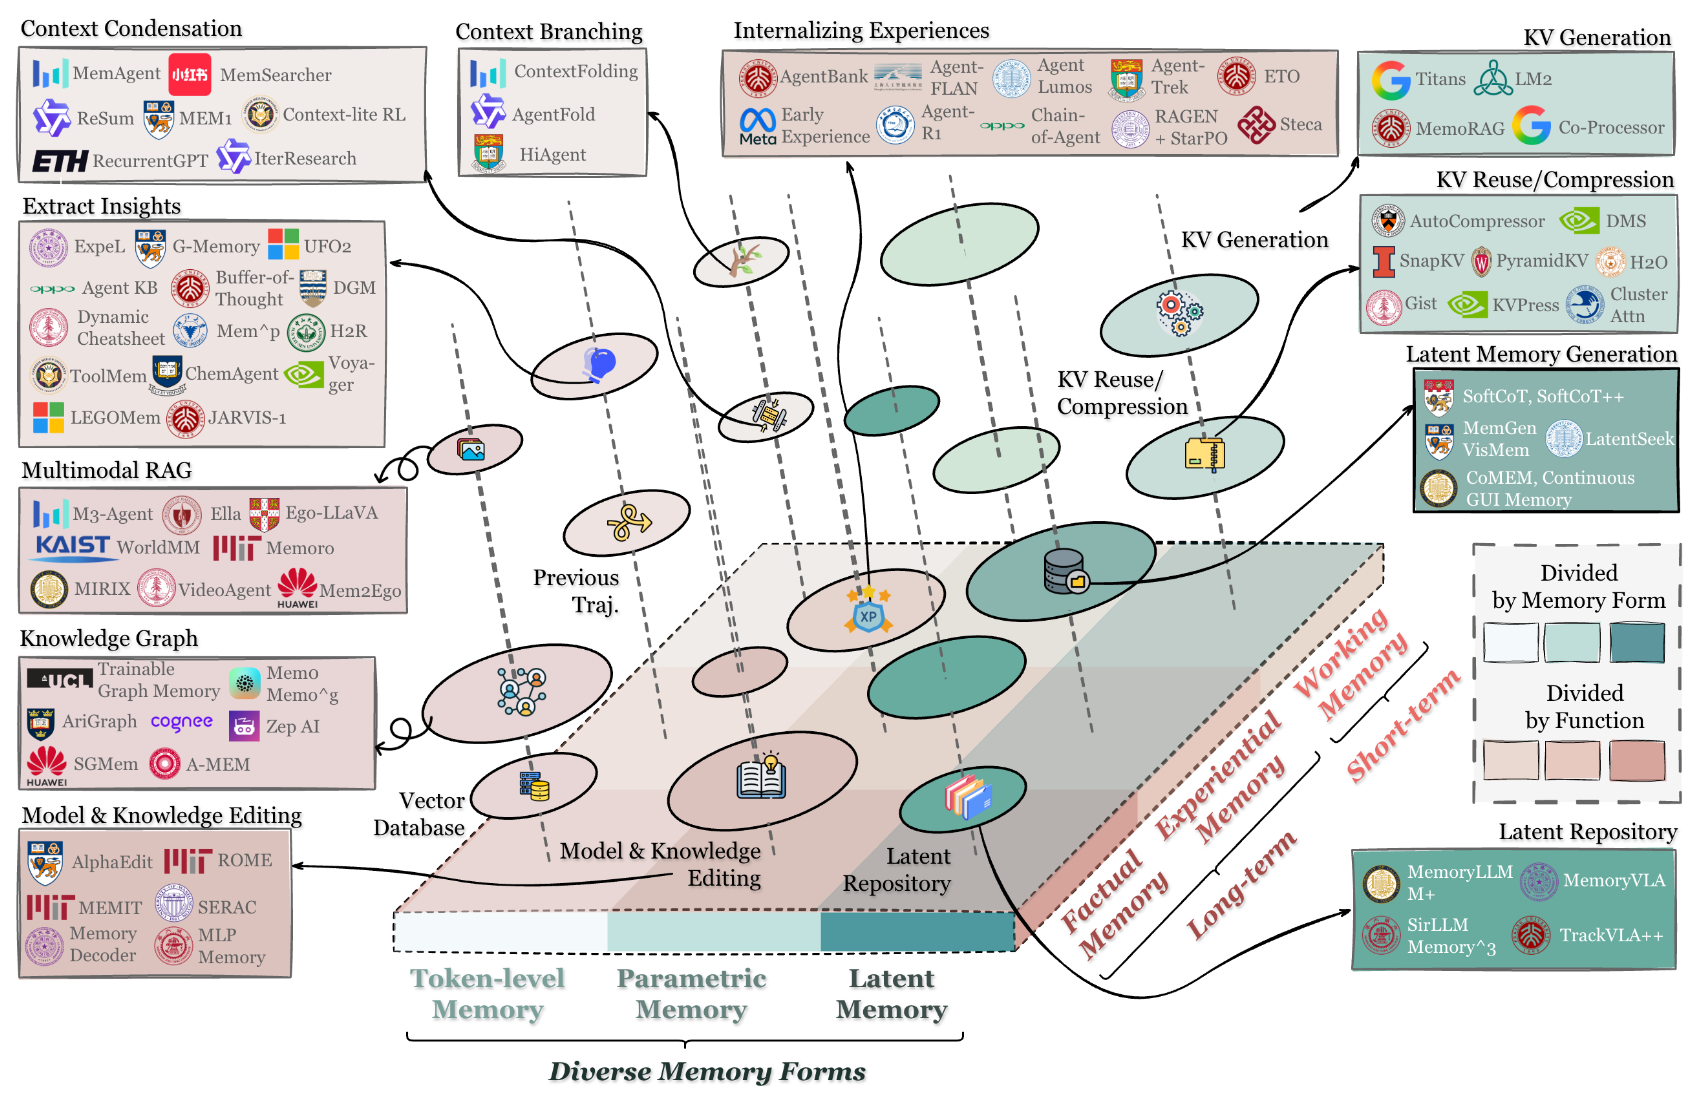
Memory in the Age of AI Agents
Yuyang Hu*, Shichun Liu*, Yanwei Yue*, Guibin Zhang*, et al.
CoRR 2025
A comprehensive survey that organizes agent memory research through forms, functions, and dynamics, and summarizes benchmarks, frameworks, and future directions.
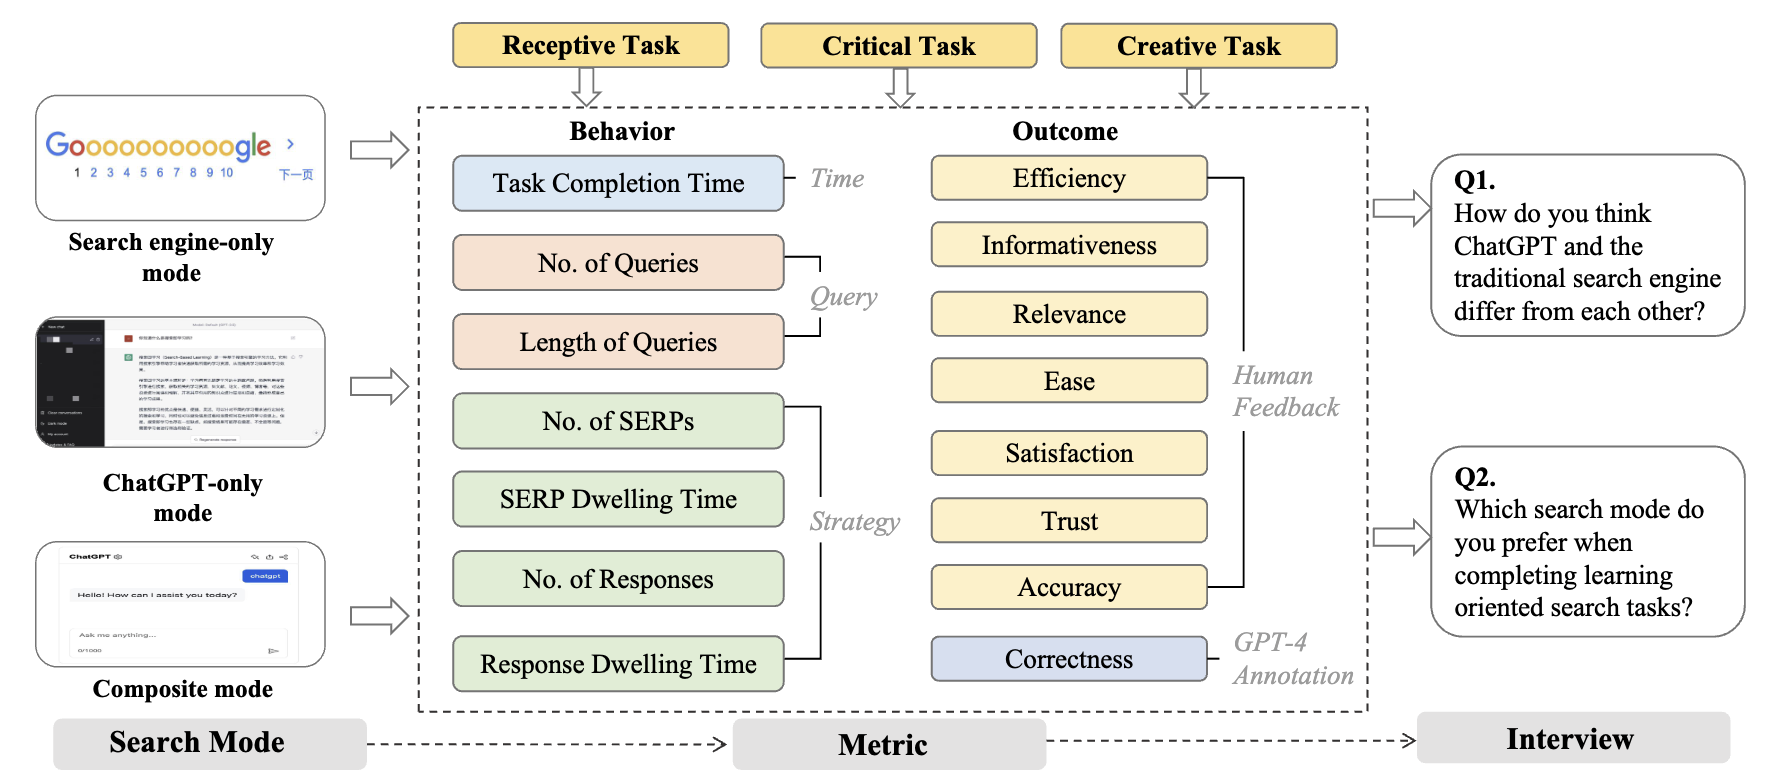
Investigating Users' Search Behavior and Outcome with ChatGPT in Learning-oriented Search Tasks
Sijie Liu, Yuyang Hu, Zihang Tian, Zhe Jin, et al.
SIGIR-AP 2024
A user study comparing traditional search, ChatGPT, and their combination for learning-oriented search tasks across different cognitive complexity levels.